AI Lip Sync
Lip sync AI re-animates a mouth so it matches a new audio track, which powers two workflows: dubbing an existing video with different speech, and animating a single photo into a full talking video. Arteza's avatar studio hosts several lip sync engines, from Sync-3's 4K video dubbing to OmniHuman's photo-plus-audio avatars, under one credit balance.
Lip synced on Arteza
A portrait driven by an audio track. Hover or tap to watch the mouth follow the speech.
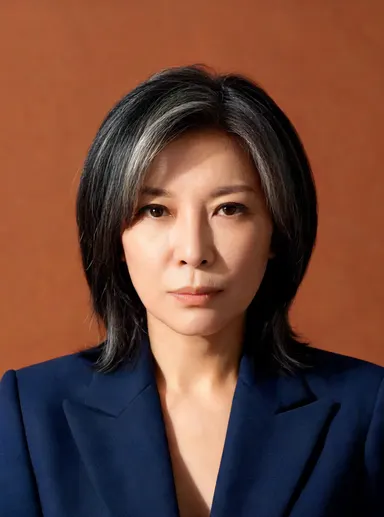 OmniHuman v1.5 3c
Studio portrait of a 40-year-old Japanese woman with silver-streaked bob, wearing a structured indigo blazer, warm terracotta backdrop, soft butterfly lighting, photorealistic, shoulders-up framing, direct confident gaze.
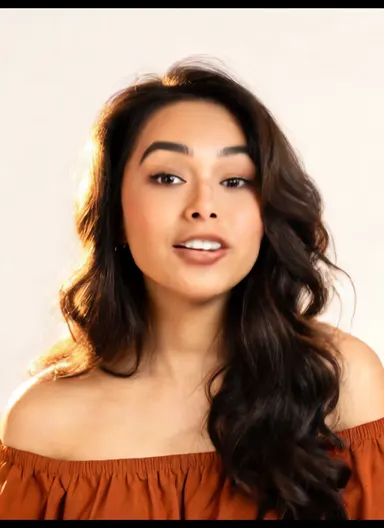 Wan 2.2 S2V 4c
Studio portrait of a 25-year-old Peruvian woman with long dark waves, wearing an off-shoulder rust-orange blouse, ivory backdrop, golden-hour rim lighting, photorealistic, shoulders-up, bright curious expression.
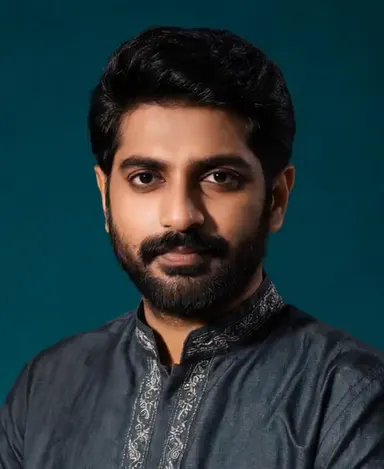 Infini Talk 5c
Studio portrait of a 38-year-old Indian man with neat beard, wearing a charcoal kurta with subtle embroidery, deep teal backdrop, split studio lighting, photorealistic, shoulders-up, composed and attentive expression.
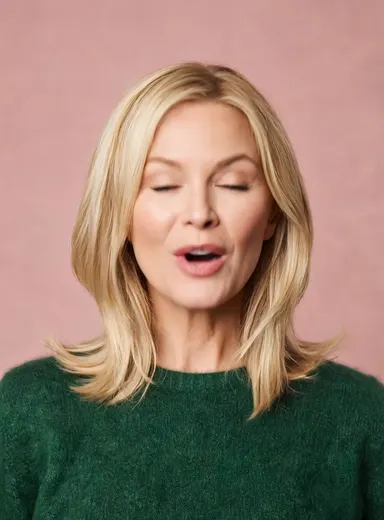 Fabric 1.0 2c
Studio portrait of a 45-year-old Swedish woman with blonde lob haircut, wearing a forest-green cashmere sweater, dusty rose backdrop, soft beauty-dish lighting, photorealistic, shoulders-up, genuine warm gaze.
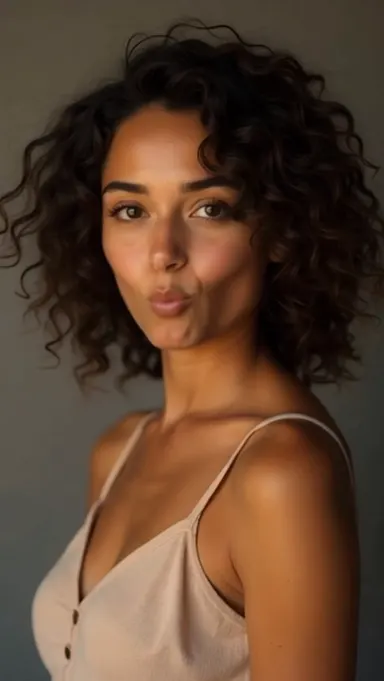 Sync-3 Lipsync 3c
Studio portrait of a 32-year-old South Korean man with undercut hair, wearing a crisp sky-blue dress shirt, off-white backdrop, cool cinematic LED lighting, photorealistic, shoulders-up, relaxed professional expression.
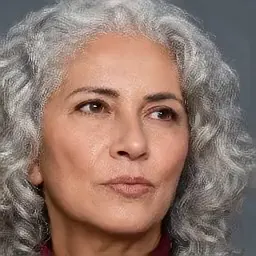 SadTalker 8c
Studio portrait of a 55-year-old Brazilian woman with silver curls, wearing a deep burgundy turtleneck, slate-grey backdrop, soft front-fill studio lighting, photorealistic, shoulders-up, thoughtful neutral expression.
How it works
Provide the face
Upload a video to dub, or a single portrait photo to animate. Front-facing, well-lit faces with the mouth clearly visible sync most convincingly.
Add the audio
Upload a recording, or generate speech first in the audio studio with text to speech or a cloned voice. The model maps each speech sound to the matching mouth shape.
Generate the synced video
The model regenerates the mouth region frame by frame, or animates the whole face from the photo, so the lips, jaw and expressions move in time with the sound.
Models you can use right now
Every model below is live on Arteza with its current credit cost, pulled from the same pricing engine the studio uses at generation time.
Frequently asked questions
Can I lip sync a photo, or do I need a video?
Both workflows are supported. Sync-3 Lipsync dubs existing videos with new audio at up to 4K. OmniHuman v1.5, Kling Avatar v2 and Infini Talk animate a single photo plus an audio file into a complete talking video.
Does AI lip sync work in any language?
Generally yes. The model maps sounds to mouth shapes rather than understanding the words, so it can sync mouths to most spoken languages, which is why lip sync is the backbone of video translation and localized content.
What inputs give the best results?
Clean speech audio without heavy music, and a face that is reasonably large, front-facing and unobstructed. Fast head turns, hands over the mouth and extreme angles are where artifacts appear.
Can I use someone else's face?
Only with their consent. Lip sync is widely used for legitimate dubbing, translation and avatar content, but you should only animate the likeness of people who have agreed to it.